
For those who enjoy rooting for the underdog, the latest MLPerf benchmark results will disappoint: Nvidia’s GPUs have dominated the competition yetagain. This includes chart-topping performance on the latest and most demanding benchmark, pretraining the Llama 3.1 403B large language model. That said, the computers built around the newest AMD GPU, MI325X, matched the performance of Nvidia’s H200, Blackwell’s predecessor, on the most popular LLM fine-tuning benchmark. This suggests that AMD is one generation behind Nvidia.
MLPerf training is one of the machine learning competitions run by the MLCommons consortium. “AI performance sometimes can be sort of the Wild West. MLPerf seeks to bring order to that chaos,” says Dave Salvator, director of accelerated computing products at Nvidia. “This is not an easy task.”
The competition consists of six benchmarks, each probing a different industry-relevant machine learning task. The benchmarks are content recommendation, large language model pretraining, large language model fine-tuning, object detection for machine vision applications, image generation, and graph node classification for applications such as fraud detection and drug discovery.
The large language model pretraining task is the most resource intensive, and this round it was updated to be even more so. The term “pretraining” is somewhat misleading—it might give the impression that it’s followed by a phase called “training.” It’s not. Pretraining is where most of the number crunching happens, and what follows is usually fine-tuning, which refines the model for specific tasks.
In previous iterations, the pretraining was done on the GPT3 model. This iteration, it was replaced by Meta’s Llama 3.1 403B, which is more than twice the size of GPT3 and uses a four times larger context window. The context window is how much input text the model can process at once. This larger benchmark represents the industry trend for ever larger models, as well as including some architectural updates.
Blackwell Tops the Charts, AMD on Its Tail
For all six benchmarks, the fastest training time was on Nvidia’s Blackwell GPUs. Nvidia itself submitted to every benchmark (other companies also submitted using various computers built around Nvidia GPUs). Nvidia’s Salvator emphasized that this is the first deployment of Blackwell GPUs at scale and that this performance is only likely to improve. “We’re still fairly early in the Blackwell development life cycle,” he says.
This is the first time AMD has submitted to the training benchmark, although in previous years other companies have submitted using computers that included AMD GPUs. In the most popular benchmark, LLM fine-tuning, AMD demonstrated that its latest Instinct MI325X GPU performed on par with Nvidia’s H200s. Additionally, the Instinct MI325X showed a 30 percent improvement over its predecessor, the Instinct MI300X. (The main difference between the two is that MI325X comes with 30 percent more high-bandwidth memory than MI300X.)
For it’s part, Google submitted to a single benchmark, the image-generation task, with its Trillium TPU.
The Importance of Networking
Of all submissions to the LLM fine-tuning benchmarks, the system with the largest number of GPUs was submitted by Nvidia, a computer connecting 512 B200s. At this scale, networking between GPUs starts to play a significant role. Ideally, adding more than one GPU would divide the time to train by the number of GPUs. In reality, it is always less efficient than that, as some of the time is lost to communication. Minimizing that loss is key to efficiently training the largest models.
This becomes even more significant on the pretraining benchmark, where the smallest submission used 512 GPUs, and the largest used 8,192. For this new benchmark, the performance scaling with more GPUs was notably close to linear, achieving 90 percent of the ideal performance.
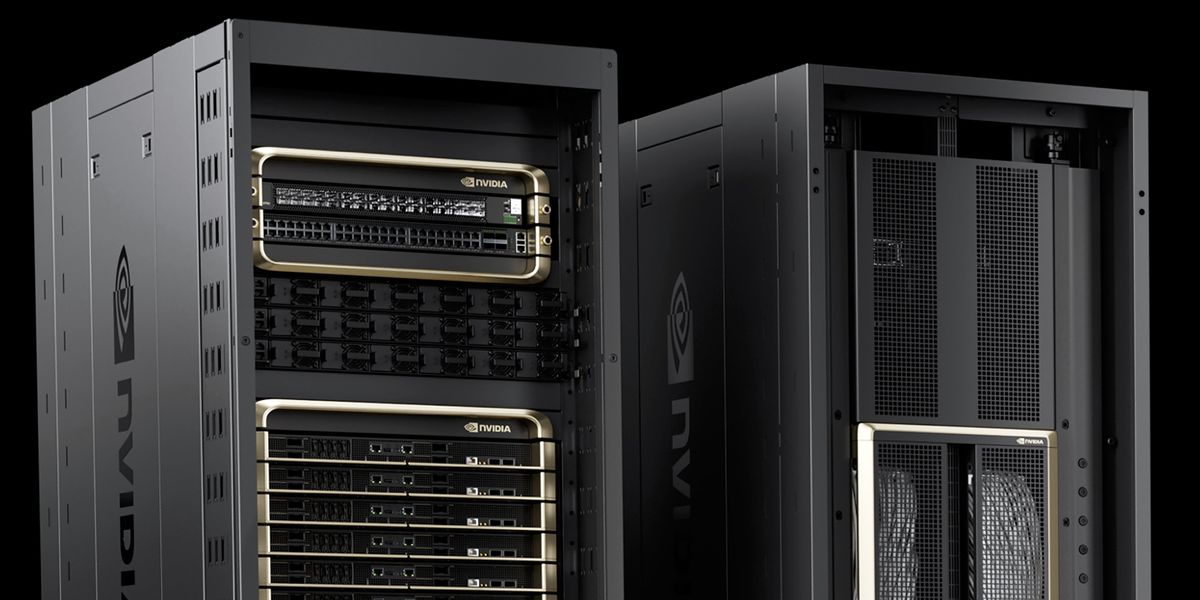
Nvidia’s Salvator attributes this to the NVL72, an efficient package that connects 36 Grace CPUs and 72 Blackwell GPUs with NVLink, to form a system that “acts as a single, massive GPU,” the datasheet claims. Multiple NVL72s were then connected with InfiniBand network technology.
Notably, the largest submission for this round of MLPerf—at 8192 GPUs—is not the largest ever, despite the increased demands of the pretraining benchmark. Previous rounds saw submissions with over 10,000 GPUs. Kenneth Leach, principal AI and machine learning engineer at Hewlett Packard Enterprise, attributes the reduction to improvements in GPUs, as well as networking between them. “Previously, we needed 16 server nodes [to pretrain LLMs], but today we’re able to do it with 4. I think that’s one reason we’re not seeing so many huge systems, because we’re getting a lot of efficient scaling.”
One way to avoid the losses associated with networking is to put many AI accelerators on the same huge wafer, as done by Cerebras, which recently claimed to beat Nvidia’s Blackwell GPUs by more than a factor of two on inference tasks. However, that result was measured by Artificial Analysis, which queries different providers without controlling how the workload is executed. So its not an apples-to-apples comparison in the way the MLPerf benchmark ensures.
A Paucity of Power
The MLPerf benchmark also includes a power test, measuring how much power is consumed to achieve each training task. This round, only a single submitter—Lenovo—included a power measurement in its submission, making it impossible to make comparisons across performers. The energy it took to fine-tune an LLM on two Blackwell GPUs was 6.11 gigajoules, or 1,698 kilowatt-hours, or roughly the energy it would take to heat a small home for a winter. With growing concerns about AI’s energy use, the power efficiency of training is crucial, and this author is perhaps not alone in hoping more companies submit these results in future rounds.
From Your Site Articles
Related Articles Around the Web
